# The Problems of "Schema-First" GraphQL Server Development
URL: https://www.prisma.io/blog/the-problems-of-schema-first-graphql-development-x1mn4cb0tyl3
Published: 2019-01-31
Authors: Nikolas Burk
Series: Code-first GraphQL server development with Nexus
Description: Explore the limitations of schema-first GraphQL server development and the case for code-first alternatives like GraphQL Nexus.
> Blog posts describe Prisma as it was on the date shown and are not kept current. Before implementing from a post, check the documentation index at https://www.prisma.io/docs/llms.txt and the changelog at https://www.prisma.io/changelog.md.
> For an index of every published post, fetch https://www.prisma.io/blog/llms.txt.
Tooling for GraphQL server development has exploded in the last two years. We believe that the need for most tools
comes from the popular schema-first approach — and can be solved by an alternative: code-first.
## Overview: From schema-first to code-first [#overview-from-schema-first-to-code-first]
This article gives an overview of the current state of the GraphQL server development space. Here's a quick outline of what is covered:
1. What does "schema-first" mean in this article?
2. The evolution of GraphQL server development
3. Analyzing the problems of SDL-first development
4. Conclusion: SDL-first could potentially work, but requires a myriad of tools
5. Code-first: A language-idiomatic way for GraphQL server development
While this article mostly gives examples of the JavaScript ecosystem, much of it applies to GraphQL server development in other language ecosystems as well.
***
## What does "schema-first" mean in this article? [#what-does-schema-first-mean-in-this-article]
The term *schema-first* is quite ambiguous and in general conveys a very positive idea: **Making schema design a priority in the development process.**
Thinking about the schema (and therefore the API) before implementing it typically results in better API design. If schema design falls short, there's a risk of ending up with an API that's an outcome of how the backend is implemented, ignoring the primitives of the business domain and needs of API consumers.
In this article, we’re going to discuss the drawbacks of a development process where the GraphQL schema is first defined *manually* in SDL, with the resolvers implemented afterwards. In this methodology, the [SDL](https://www.prisma.io/blog/graphql-sdl-schema-definition-language-6755bcb9ce51) is the *source of truth* for the API. **To clarify the distinction between schema-first design and this specific implementation approach, we'll refer to it as *SDL-first* from here on.**
In contrast, **code-first** (also sometimes called *resolver-first*) is a process where the GraphQL schema is implemented *programmatically* and the SDL version of the schema is a *generated artifact* of that. With code-first, you can still pay a lot of attention to upfront schema design!
***
## The evolution of GraphQL server development [#the-evolution-of-graphql-server-development]
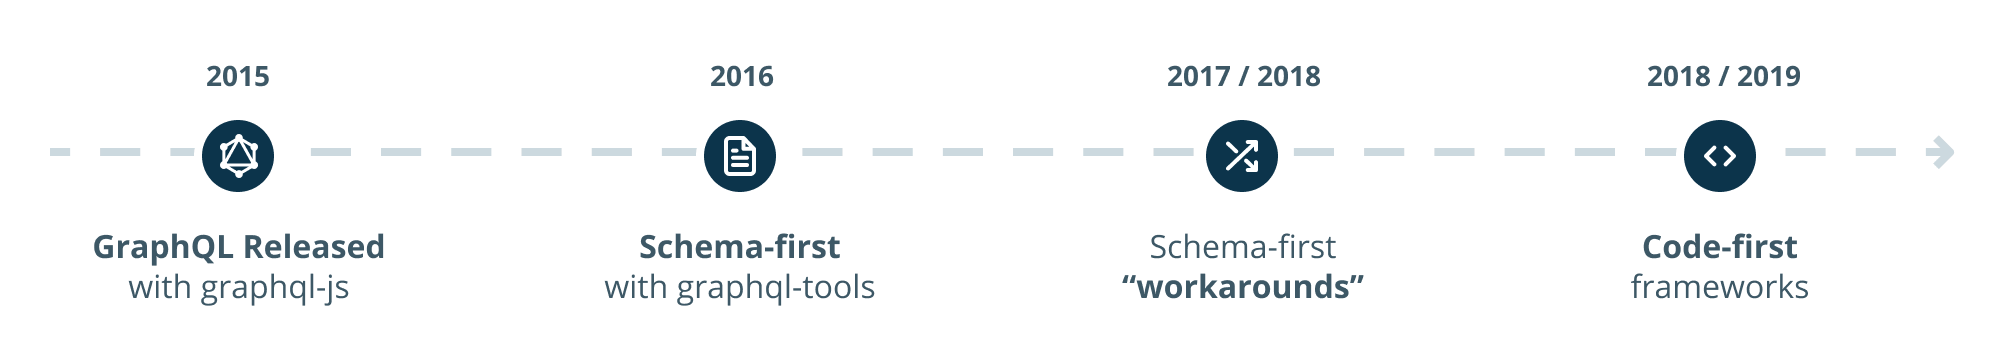
### Phase 1: The early days with `graphql-js` [#phase-1-the-early-days-with-graphql-js]
When GraphQL was released in 2015, the tooling ecosystem was scarce. There was only the official [specification](https://spec.graphql.org/June2018) and its reference implementation in JavaScript: [`graphql-js`](https://github.com/graphql/graphql-js). Until today, `graphql-js` is used in the most popular GraphQL servers, like `apollo-server`, `express-graphql`, and `graphql-yoga`.
When using `graphql-js` to build a GraphQL server, the [GraphQL schema](https://www.prisma.io/blog/graphql-server-basics-the-schema-ac5e2950214e) is defined as a plain JavaScript object:
```js
const { GraphQLSchema, GraphQLObjectType, GraphQLString } = require('graphql')
const schema = new GraphQLSchema({
query: new GraphQLObjectType({
name: 'Query',
fields: {
hello: {
type: GraphQLString,
args: {
name: { type: GraphQLString },
},
resolve: (_, args) => `Hello ${args.name || 'World!'}`,
},
},
}),
})
```
```js
const { GraphQLSchema, GraphQLObjectType, GraphQLString, GraphQLID } = require('graphql')
const UserType = new GraphQLObjectType({
name: 'User',
fields: {
id: { type: GraphQLID },
name: { type: GraphQLString },
},
})
const schema = new GraphQLSchema({
query: new GraphQLObjectType({
name: 'Query',
fields: {
user: {
type: UserType,
args: {
id: { type: GraphQLID },
},
resolve: (_, { id }) => {
return fetchUserById(id) // fetch the user, e.g. from a database
},
},
},
}),
mutation: new GraphQLObjectType({
name: 'Mutation',
fields: {
createUser: {
type: UserType,
args: {
name: { type: GraphQLString },
},
resolve: (_, { name }) => {
return createUser(name) // create a user, e.g. in a database
},
},
},
}),
})
```
As can be seen from these examples, the API for creating GraphQL schemas with `graphql-js` is very verbose. The SDL representation of the schema is a lot more concise and easier to grasp:
```graphql
type Query {
hello(name: String): String
}
```
```graphql
type User {
id: ID
name: String
}
type Query {
user(id: ID): User
}
type Mutation {
createUser(name: String): User
}
```
> Learn more about building GraphQL schemas with `graphql-js` in [this](https://www.prisma.io/blog/graphql-server-basics-the-schema-ac5e2950214e) article.
### Phase 2: Schema-first popularized by `graphql-tools` [#phase-2-schema-first-popularized-by-graphql-tools]
To ease development and increase the visibility into the actual API definition, Apollo started building the [`graphql-tools`](https://github.com/apollographql/graphql-tools) library in March 2016 ([here](https://github.com/apollographql/graphql-tools/commit/fe17783a6a166278195d172beb5670b045fb300d)'s the first commit).
The goal was to separate the schema *definition* from the actual *implementation*, this led to the currently popular *schema-driven* or *schema-first* / *SDL-first* development process:
1. Manually write the GraphQL schema definition in GraphQL SDL
2. Implement the required resolver functions
With this approach, the examples from above now look like this:
```js
const { makeExecutableSchema } = require('graphql-tools')
const typeDefs = `
type Query {
hello(name: String): String
}
`
const resolvers = {
Query: {
hello: (_, args) => `Hello ${args.name || 'World!'}`,
},
}
const schema = makeExecutableSchema({
typeDefs,
resolvers,
})
```
```js
const { makeExecutableSchema } = require('graphql-tools')
const typeDefs = `
type User {
id: ID
name: String
}
type Query {
user(id: ID): User
}
type Mutation {
createUser(name: String): User
}
`
const resolvers = {
Query: {
user: (_, args) => fetchUserById(args.id), // fetch the user, e.g. from a database
},
Mutation: {
createUser: (_, args) => createUser(args.name), // create a user, e.g. in a database
},
}
const schema = makeExecutableSchema({
typeDefs,
resolvers,
})
```
These code snippets are 100% equivalent to the code above that uses `graphql-js`, except they're a lot more readable and easier to understand.
Readability is not the only advantage of SDL-first:
* The approach is **easy to understand** and **great for building things quickly**
* As every new API operation first needs to be manifested in the schema definition, **GraphQL schema design is not an after-thought**
* The schema definition can serve as **API documentation**
* The schema definition can serve as a **communication tool between frontend and backend teams** — frontend developers are getting empowered and more involved in the API design
* The schema definition enables **quick mocking of an API**
### Phase 3: Developing new tools to "fix" SDL-first [#phase-3-developing-new-tools-to-fix-sdl-first]
While SDL-first has many advantages, the last two years have shown that it's challenging to scale it to larger projects. There are a number of problems that arise in more complex environments (we'll discuss these in detail in the next section).
The problems, by themselves, are indeed mostly solvable — the *actual* problem is that solving them requires using (and *learning*) many additional tools. During the past two years, a myriad of tools have been released that are trying to improve the workflows around SDL-first development: from editor plugins, to CLIs to language libraries.
The overhead in learning, managing, and integrating all these tools slows developers down, and makes it difficult to keep up with the GraphQL ecosystem.
***
## Analyzing the problems of SDL-first development [#analyzing-the-problems-of-sdl-first-development]
Let's now dive a bit deeper into the problem areas around SDL-first development. Note that most of these issues particularly apply to the current JavaScript ecosystem.
### Problem 1: Inconsistencies between schema definition and resolvers [#problem-1-inconsistencies-between-schema-definition-and-resolvers]
With SDL-first, the schema definition *must* match the exact structure of the resolver implementation. This means developers need to ensure that the schema definition is in sync with the resolvers at all times!
While this is already a challenge even for small schemas, it becomes practically impossible as schemas grow to hundreds or thousands of lines (for reference, the [GitHub GraphQL schema](https://gist.github.com/nikolasburk/15f30bb3e19e5bf8329ff52787fa72b5) has more than 10k lines).
**Tools/Solution:** There are a few tools that help keeping schema definition and resolvers in sync. For example, through code generation with libraries like [`graphqlgen`](https://github.com/prisma/graphqlgen) or [`graphql-code-generator`](https://github.com/dotansimha/graphql-code-generator).
### Problem 2: Modularization of GraphQL schemas [#problem-2-modularization-of-graphql-schemas]
When writing large GraphQL schemas, you typically don't want all of your GraphQL type definitions to reside in the same file. Instead, you want to split them up into smaller parts (e.g. according to *features* or *products*).
[Post on X](https://x.com/i/status/1058832149585874944)
**Tools/Solution:** Tools like [`graphql-import`](https://github.com/prisma/graphql-import) or the more recent [`graphql-modules`](https://graphql-modules.com/) library help with this. `graphql-import` uses a custom import syntax written as SDL comments. `graphql-modules` is a toolset to help with *schema separation*, *resolver composition*, and the implementation of a *scalable structure* for GraphQL servers.
### Problem 3: Redundancy in schema definitions (code reuse) [#problem-3-redundancy-in-schema-definitions-code-reuse]
Another question is how to *reuse* SDL definitions. A common example for this issue are Relay-style connections. While providing a powerful approach to implement pagination, they require *a lot* of boilerplate and repeated code.
There's currently no tooling that helps with this issue. Developers can write custom tools to reduce the need for repeating code, but the problem lacks a generic solution at the moment.
### Problem 4: IDE support & developer experience [#problem-4-ide-support--developer-experience]
The GraphQL schema is based on a strong type system which can be a tremendous benefit during development because it allows for static analysis of your code. Unfortunately, SDL is typically represented as plain *strings* in your programs, meaning the tooling doesn't recognize any structure inside of it.
The question then becomes how to leverage the GraphQL types in your editor workflows to benefit from features like auto-completion and build-time error checks for your SDL code.
**Tools/Solution:** The [`graphql-tag`](https://github.com/apollographql/graphql-tag) library exposes the `gql` function that turns a GraphQL string into an AST and therefore enables static analysis and the features following from that. Aside from that, there are various editor plugins, such as the [GraphQL](https://marketplace.visualstudio.com/items?itemName=Prisma.vscode-graphql) or [Apollo GraphQL](https://marketplace.visualstudio.com/items?itemName=apollographql.vscode-apollo) plugins for VS Code.
### Problem 5: Composing GraphQL schemas [#problem-5-composing-graphql-schemas]
The idea of modularizing schemas also leads to another question: How to *compose* a number of existing (and distributed) schemas into a single schema.
**Tools/Solution:** The most popular approach for schema composition has been [schema stitching](https://www.apollographql.com/docs/graphql-tools/schema-stitching.html) which is also part of the aforementioned `graphql-tools` library. To have more control over how exactly the schema is composed, you can also use [schema delegation](https://www.prisma.io/blog/graphql-schema-stitching-explained-schema-delegation-4c6caf468405) (which is a *subset* of schema stitching) directly.
## Conclusion: SDL-first could *potentially* work, but requires a myriad of tools [#conclusion-sdl-first-could-potentially-work-but-requires-a-myriad-of-tools]
After having explored the problem areas and various tools developed to solve them, it seems like that SDL-first development *could* work eventually – but also that it requires developers to learn and use a myriad of additional tools.
[Post on X](https://x.com/i/status/1065171444370481152)
### Workarounds, workarounds, workarounds, ... [#workarounds-workarounds-workarounds-]
At Prisma, we played a major role in pushing the GraphQL ecosystem forward. Many of the mentioned tools have been built by our engineers and community members.
After several months of development and close interactions with the GraphQL community, we've come to realize that we're only fixing symptoms. It's like fighting a [Hydra](https://en.wikipedia.org/wiki/Lernaean_Hydra) – solving one problem leads to several new ones.
### Ecosystem lock-in: Buying into an entire toolchain [#ecosystem-lock-in-buying-into-an-entire-toolchain]
We really appreciate the work of our friends at Apollo who constantly work on improving the development workflows around SDL-first development.
Another popular example for building GraphQL servers in a SDL-first way is AWS AppSync. It diverges a bit from the Apollo model since resolvers are (typically) not implemented programmatically but auto-generated from the schema definition.
While the community greatly benefits from so many tools, there's a risk of ecosystem lock-in for developers when they need to take a full bet on the toolchain of a certain organization. The *real* solution probably would be to bake many of the SDL-first opinions into the GraphQL core itself – which is unlikely to happen in the foreseeable future.
### SDL-first disregards individual characteristics of programming languages [#sdl-first-disregards-individual-characteristics-of-programming-languages]
Another problematic aspect of SDL-first is that it disregards the individual features of a programming language by imposing similar principles, no matter which programming language is used.
Code-first approaches work really well in other languages: the Scala library [`sangria-graphql`](https://github.com/sangria-graphql/sangria) leverages Scala's powerful type system to elegantly build GraphQL schemas, [`graphlq-ruby`](https://github.com/rmosolgo/graphql-ruby) uses many of the awesome DSL features of the Ruby language.
***
## Code-first: A language-idiomatic way for GraphQL server development [#code-first-a-language-idiomatic-way-for-graphql-server-development]
### The only tool you need is your programming language [#the-only-tool-you-need-is-your-programming-language]
Most of the SDL-first problems come from the fact that we need to *map the manually written SDL schema to a programming language*. This mapping is what causes the need for additional tools. If we follow the SDL-first path, the required tools will need to be reinvented for *every* language ecosystem, and *look* differently for each one as well.
Instead of increasing the complexity of GraphQL server development with more tools, we should strive for a simpler development model. Ideally one, that lets developers leverage the programming language they're already using – this is the idea of *code-first*.
### What exactly is code-first? [#what-exactly-is-code-first]
Remember the initial example of defining a schema in `graphql-js`? This is the *essence* of what code-first means. There is no manually maintained version of your schema definition, instead the SDL is *generated* from the code that implements the schema.
While the API of `graphql-js` is very verbose, there are many popular frameworks in other languages that work based on the code-first approach, such as the already mentioned [`graphlq-ruby`](https://github.com/rmosolgo/graphql-ruby) [`sangria-graphql`](https://github.com/sangria-graphql/sangria), as well as [`graphene`](https://github.com/graphql-python/graphene) for Python or [`absinthe-graphql`](https://github.com/absinthe-graphql/absinthe) for Elixir.
[Post on X](https://x.com/i/status/1080433403852292097)
### Code-first in practice [#code-first-in-practice]
While this article is mostly about understanding the issues of SDL-first, here's a little teaser for what building a GraphQL schema with a code-first framework looks like:
```ts
const Query = objectType('Query', t => {
t.string('hello', {
args: { name: stringArg() },
resolve: (_, { name }) => `Hello ${name || `World`}!`,
})
})
const schema = makeSchema({
types: [Query],
outputs: {
schema: './schema.graphql'),
typegen: './typegen.ts',
},
})
```
```ts
const User = objectType('User', t => {
t.id('id')
t.string('name', { nullable: true })
})
const Query = objectType('Query', t => {
t.field('user', 'User', {
args: { id: idArg() },
resolve: (_, { id }) => fetchUserById(id) // fetch the user, e.g. from a database
})
})
const Mutation = objectType('Mutation', t => {
t.field('createUser', 'User', {
args: { name: stringArg() },
resolve: (_, { name }) => createUser(name) // create a user, e.g. in a database
})
})
const schema = makeSchema({
types: [User, Query, Mutation],
outputs: {
schema: './schema.graphql'),
typegen: './typegen.ts',
},
})
```
Wtih this approach, you define your GraphQL types directly in TypeScript/JavaScript. With the right setup and thanks to [intelligent code completion](https://en.wikipedia.org/wiki/Intelligent_code_completion), your editors will be able suggest the available GraphQL types, fields and arguments as you define them.
A typical editor workflow includes a development server running in the background that regenerates typings whenever files are saved.
Once all GraphQL types are defined, they're passed into a function to create a [`GraphQLSchema`](https://graphql.org/graphql-js/type/#graphqlschema) instance which can be used in your GraphQL server. By specifying the `ouputs`, you can define where the generated SDL and typings should be located.
The next parts of this article series will discuss code-first development in more detail.
### Getting the benefits of SDL-first, without needing all the tools [#getting-the-benefits-of-sdl-first-without-needing-all-the-tools]
Earlier we enumerated the benefits of SDL-first development. In fact, there's no need to compromise on most of them when using the code-first approach.
**The most important benefit of using the GraphQL schema as a crucial communication tool for frontend and backend teams remains.**
Looking at the GitHub GraphQL API as an example: GitHub uses Ruby and a code-first approach to implement their API. The SDL schema definition is generated based on the code that implements the API. However, the schema definition is still checked into version control. This makes it incredibly easy to track changes to the API during the development process and improves the communication between various teams.
Other benefits like API documentation or empowering frontend developers don't get lost with code-first approaches either.
## Code-first frameworks, coming to your IDE soon [#code-first-frameworks-coming-to-your-ide-soon]
This article was fairly theoretical and did not contain much code – we still hope we could spark your interest in code-first development. To see further practical examples and learn more about the code-first development experience, stay tuned and keep an eye on the [Prisma Twitter account](https://www.twitter.com/prisma) over the next few days 👀
> What do you think of this article? **Join the [Prisma Slack](https://slack.prisma.io)** to discusst SDL-first and code-first development with fellow GraphQL enthusiasts.
***
🙏 A huge thank you to [Sashko](https://twitter.com/stubailo) and the [Apollo](https://apollographql.com) team for their feedback on the article!